See where your AI works and where it fails
Track the quality, cost and response time of your AI features. I set up the evaluations and monitoring your team needs to improve them.
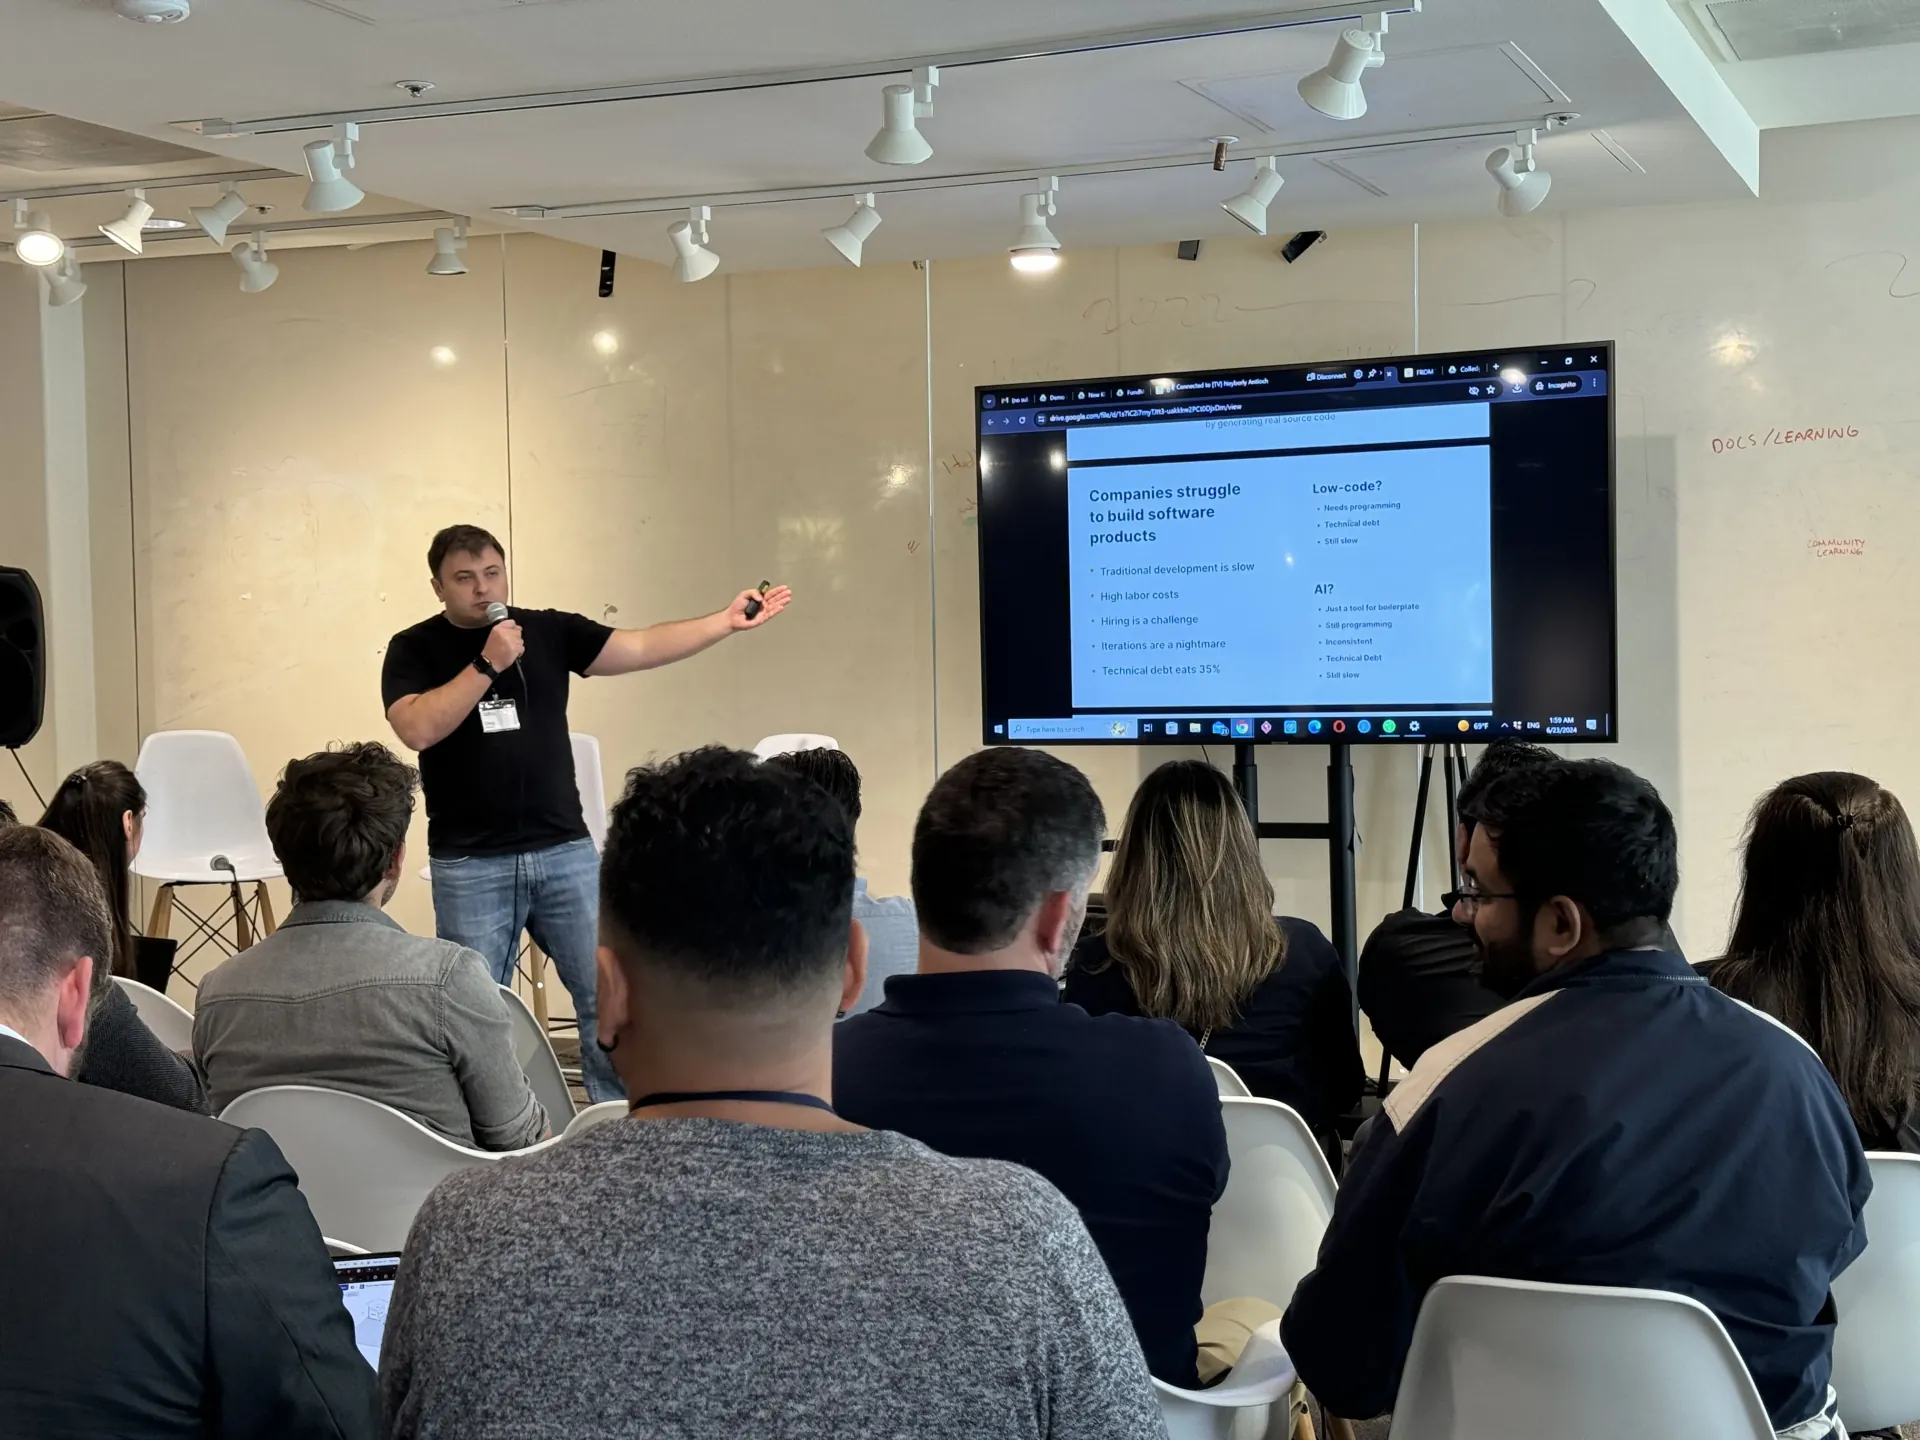
AI observability is the practice of tracing, scoring, and alerting on how a language model behaves in production: the system records every call and tool step, scores the outputs against evaluation sets, and raises an alarm when quality drifts or cost spikes. An eval is a scored test set: real cases with an agreed correct outcome, run against a prompt or model to tell you whether a change made the product better or worse. Oleg Sotnikov builds this layer for teams shipping AI features, so quality problems surface on a dashboard instead of in a support ticket.
What the Layer Actually Does
Six capabilities that turn model behavior from a rumor into data your team can act on.
Every call traced
One trace per user request: the prompt that went out, the context retrieved, tool calls, retries, tokens, and the latency of each hop. When an answer looks wrong you read the chain instead of guessing at it.
Evals from real traffic
Test cases come out of production traces — the questions your users actually ask, including the ones that failed. Synthetic examples pass tests that real customers then break. Together they grow into an LLM evaluation framework the team keeps extending.
Regression gates
A prompt or model change runs the eval suite before it ships, and a score below the line blocks the merge the same way a failing unit test does. CI for model behavior.
Quality change alerts
Set up regular checks and alert thresholds. Your team can see changes in the selected measures and investigate the requests involved.
Cost telemetry per feature
Token spend sits on the same dashboards as latency and errors, split by feature and by model. A prompt change that doubles the bill shows up the day it ships rather than on the invoice.
Incident debugging
A user reports a bad answer. You find that conversation, open its trace, and see the retrieved documents, the exact prompt, and the model that produced the response. That takes minutes instead of an afternoon of log archaeology.
How It Works
Instrument
Tracing goes into the code path you already have. Nobody rewrites the service, and you are not tied to a vendor in week one. Teams with nowhere to put it get the stack I run myself and deploy as part of engagements: Grafana, Loki, Sentry, GitLab CI.
Build the eval harness
We pull real cases out of the traces, agree what a good answer looks like for each, and turn that into a scored suite — exact checks where the output is factual or structured, model-graded rubrics where it is judgment. Thirty cases beat zero; the set grows with every incident.
Gate and hand over
The suite runs in CI on every prompt and model change, alerts fire on drift and cost, and your team gets the dashboards with a runbook for reading them. The goal is that you operate this without me.
Why Me
- AppMaster processes 11B+ tokens a month in production — evals and telemetry are how a two-person team keeps that safe
- Engagements include the platform I run myself: GitLab with in-memory CI runners, Sentry, Grafana, Loki — worth $2,000–5,000/month
- 25+ years running production systems, currently 99.99% uptime for users in 190+ countries
Where This Fits
Observability is one layer of the AI work. These are the neighbors people usually ask about next.
Frequently Asked Questions
What is AI observability?
AI observability records prompts, retrieved sources, tool calls, cost and response time. Combined with quality checks, these records help identify failures and investigate their causes.
What are AI evals?
An eval is a scored test set for model behavior. You collect real cases, write down what a correct or acceptable response looks like for each, then run a prompt or model against the whole set and get a number back. Some checks are exact — valid JSON, the right document cited, the right tool called — and the rest are graded by a stronger model against a written rubric. The purpose matches a unit test suite: find out whether a change helped before your users do.
Which LLM observability tools do you use?
That depends on your stack, and I have no vendor to sell you. If you already run a managed platform, I instrument against it rather than migrating you. If you have nothing yet, the default is the self-hosted stack I run myself and include with engagements — Grafana, Loki, Sentry — with traces and eval scores as first-class data. The tooling matters much less than having real evaluation cases and someone whose job it is to read the results.
When does a team need AI observability?
The moment an AI feature is in front of customers. Before that, a spreadsheet of test prompts is honestly enough. After that, quality drifts silently: providers update models, prompts accumulate patches, retrieval degrades as the corpus grows. Most teams start thinking about this after the first regression that reached users, and the work is cheaper and calmer done before it.
How is this different from an AI proof of concept?
A proof of concept answers whether the idea works at all, on real data, in about two weeks. Observability and evals answer whether it still works in month six, under real traffic, after nine prompt changes and a model upgrade you did not choose. The PoC earns the budget and the eval harness protects it. If the idea is not validated yet, start with the PoC and add this layer when the feature meets customers.
Find Out What Your AI Is Actually Doing
Thirty minutes on your stack, your traffic, and where quality is most likely already slipping. You leave with the first eval cases worth writing, whether or not we work together.
Free 30-minute call. If evals are not what you need yet, I will say so.
Let’s discuss your project
A free 30-minute call with Oleg to discuss your situation and choose a practical first step. No commitment.
A couple of sentences is enough: what does your company do, and what do you want to improve?
Related reading
Production AI, model quality, and the telemetry that keeps both honest.